Repository navigation
fix(crews): Crew notices report only what the platform measured - #292
Conversation


…issing

Only a read that found no file produces "handoff: missing". Any other
workspace failure fails the seat notice, so the finish stays unreported and
the next finish or the boot sweep delivers the handoff once it is readable.

Closes #226

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>
The ledger allowed one open exchange per sender and receiver, so a seat's
sign-in or permission failure was appended to whatever the Captain had open
with the person, and answering that ask closed the alert with it. While an
alert was open the Captain also could not ask the person anything new.

Alerts now open one exchange per Crew under a reserved id prefix. Migration
020 exempts that prefix from the open-pair index and the ask lookup skips
it, so an alert sits beside the Captain's ask and neither changes the
other. Replies on the alert still route to the Captain.

Closes #225

Co-Authored-By: Claude Opus 5.5 <noreply@anthropic.com>

|
Important
This repository does not receive automatic reviews because it has fewer than 10 stars. ⚙️ Run configurationConfiguration used: Repository: Jacksondr5/j5code/.coderabbit.yaml Review profile: CHILL Plan: Advanced Run ID: Comment |
 github-actions
Bot
added
vouch:trusted

Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
The notice tests this branch adds still called NodeSqliteClient.layerMemory(), which the sync replaced with NodeSqliteClient.layer({ filename: ":memory:" }).

Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>


|
[Review panel: Opus 5.5 + Astra] Bug (pre-existing, but in scope for this PR): a Crew sign-in or permission alert is saved but never delivered until something else wakes the delivery worker.
Live reproduction (Astra, in a real client on this stack):
So the alert shows up only after some unrelated send, or after a restart. The tests miss it because Suggested fix: depend on |
|
Interaction evidence from Astra, reviewed with Opus 5.5, on the merged Crews stack tip The alert has its own Inbox item. Answering it leaves the Captain's separate ask open:
The independent exchange behavior passed once delivered. End-to-end unsolicited delivery failed: the alert stayed pending with |
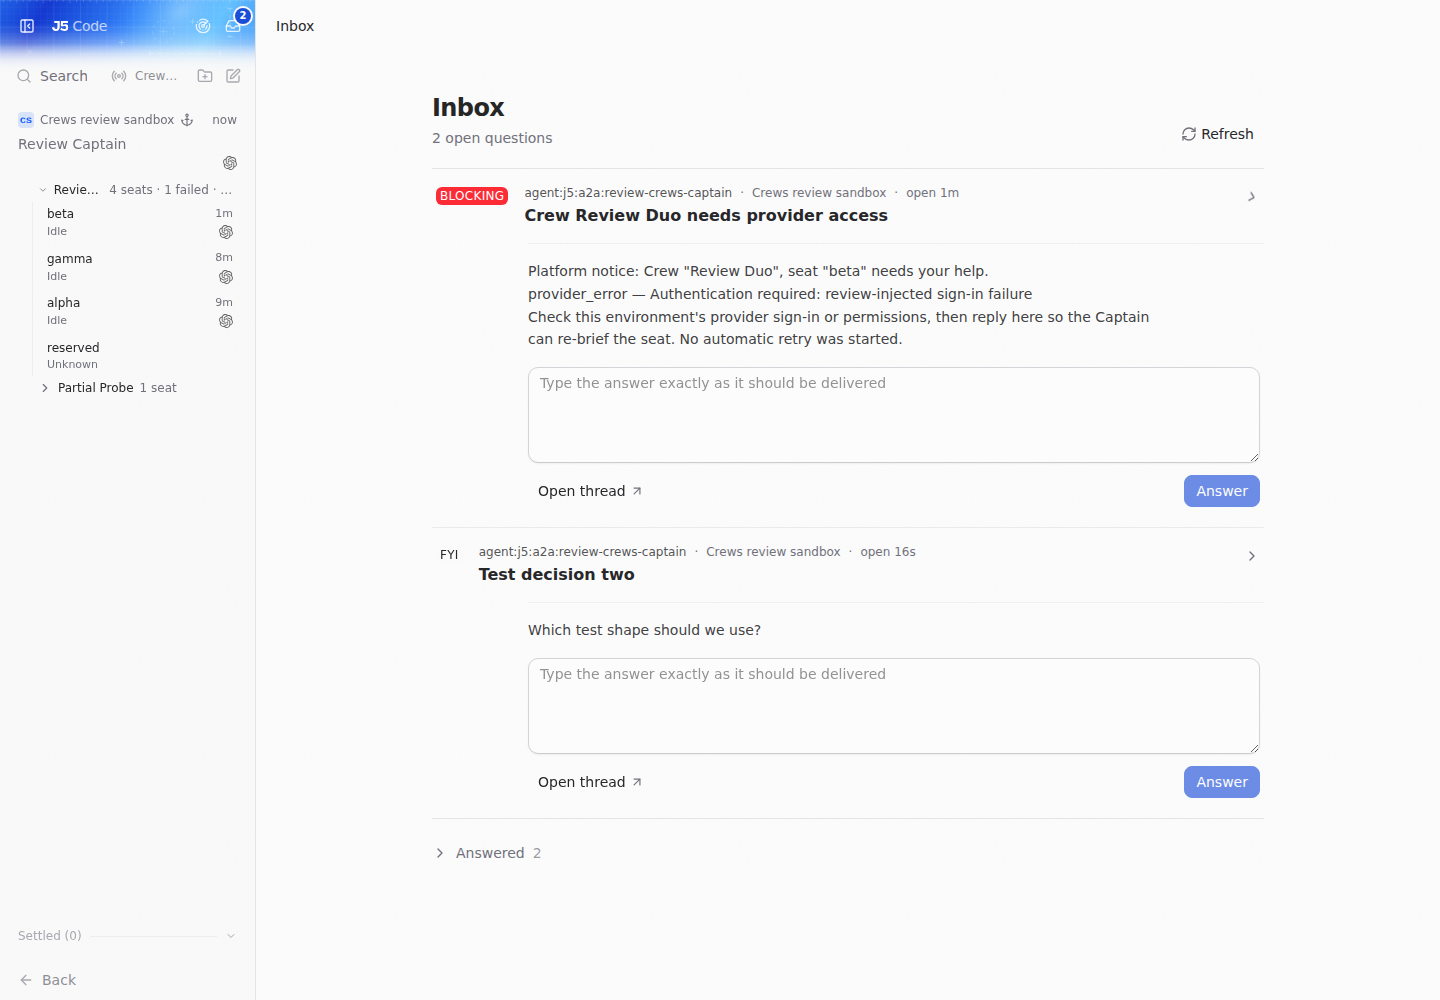
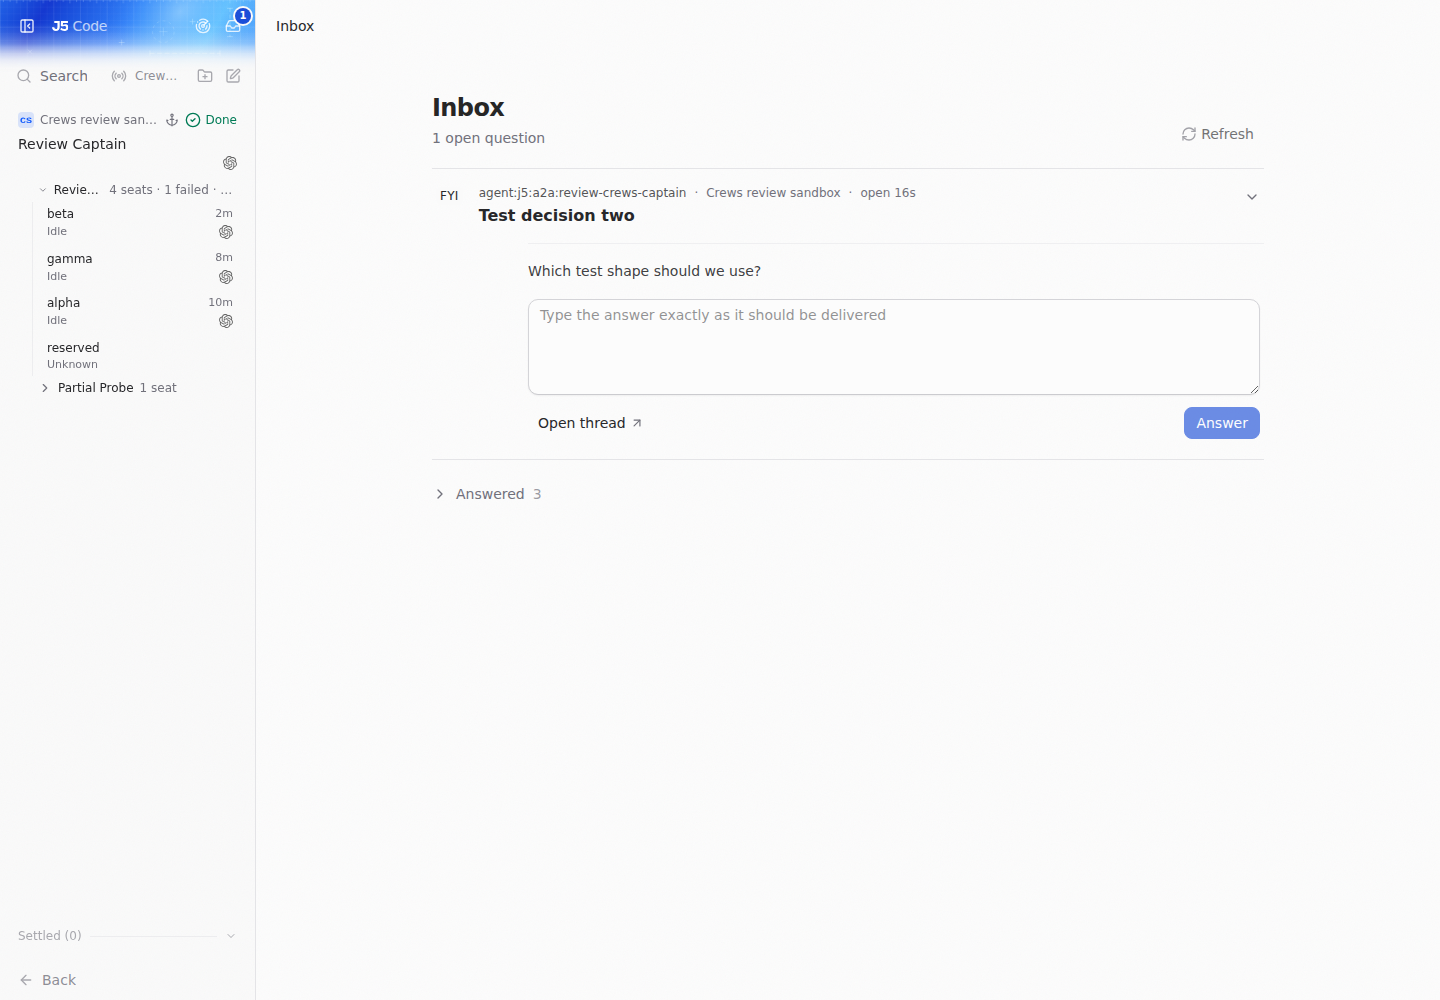
The alert committed and published to the ledger PubSub, which the delivery
worker does not read; with nothing scheduled the worker waits for a wake, so
the alert sat pending until some unrelated send woke it. It now calls
worker.notify after committing, like every other producer. The launch
reporter and the finish notifier get the one delivery worker instance from
runtimeLayer. A test counts the wakes (one on commit, none on a replay), and
another runs the worker as its daemon with no manual drain.

Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
…ish notice

Every artifact read failure other than not_found failed the notice, so a
seat whose handoff was over the read limit, a directory, or a link out of
the artifacts directory never had its finish reported, and every retry hit
the same error. The artifact workspace now names those reasons. An
oversized handoff is reported written and read by path; a directory or an
escaping link is reported unavailable with why, and the web card shows it.
Only a real I/O failure still holds the notice for a retry.

Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
|
@Jacksondr5 Both panel findings are fixed on this branch:
I also merged the latest |
github-actions
Bot
added
size:L

|
[Review panel: Opus 5.5 + Astra] Verified: the alert that never woke the delivery worker (round one) is fixed in fbcd5b7. Test note (no change needed beyond a comment): with the |
 Jacksondr5
left a comment
Jacksondr5
left a comment
There was a problem hiding this comment.
Posted by an AI agent on Jackson's behalf.
Approved. Both round-one findings are verified by the review panel (Opus 5.5 + Astra), in code and live:
- handoffs over the size limit read as written, and a directory or an out-of-root link reads as unavailable (the live cards match);
- the failure alert wakes the delivery worker by itself (99 ms, first attempt).
The daemon-test comment nit is optional.
Merge order: #292, #313, #300, then #315 (after #349 lands). #306 rebases after the stack.
|
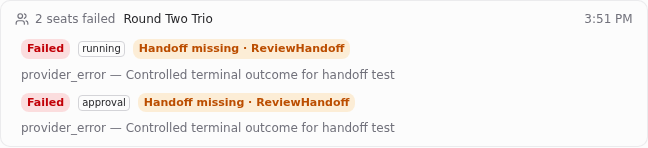
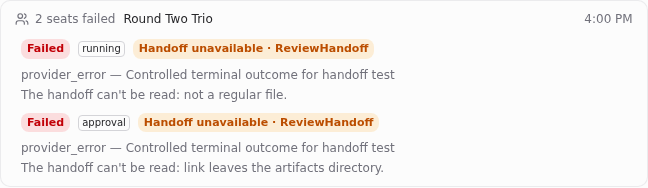
[Review panel: Opus 5.5 + Astra] Round-two web verification: all three handoff cases pass. Before and after use the same copied database, artifact fixtures, light theme, and 1440×1000 viewport. 6 MiB handoff — before: reported missing.
6 MiB handoff — after: reported written, without an inline body.
Directory and escaping symlink — before: both reported missing.
Directory and escaping symlink — after: unavailable, with a reason for each.
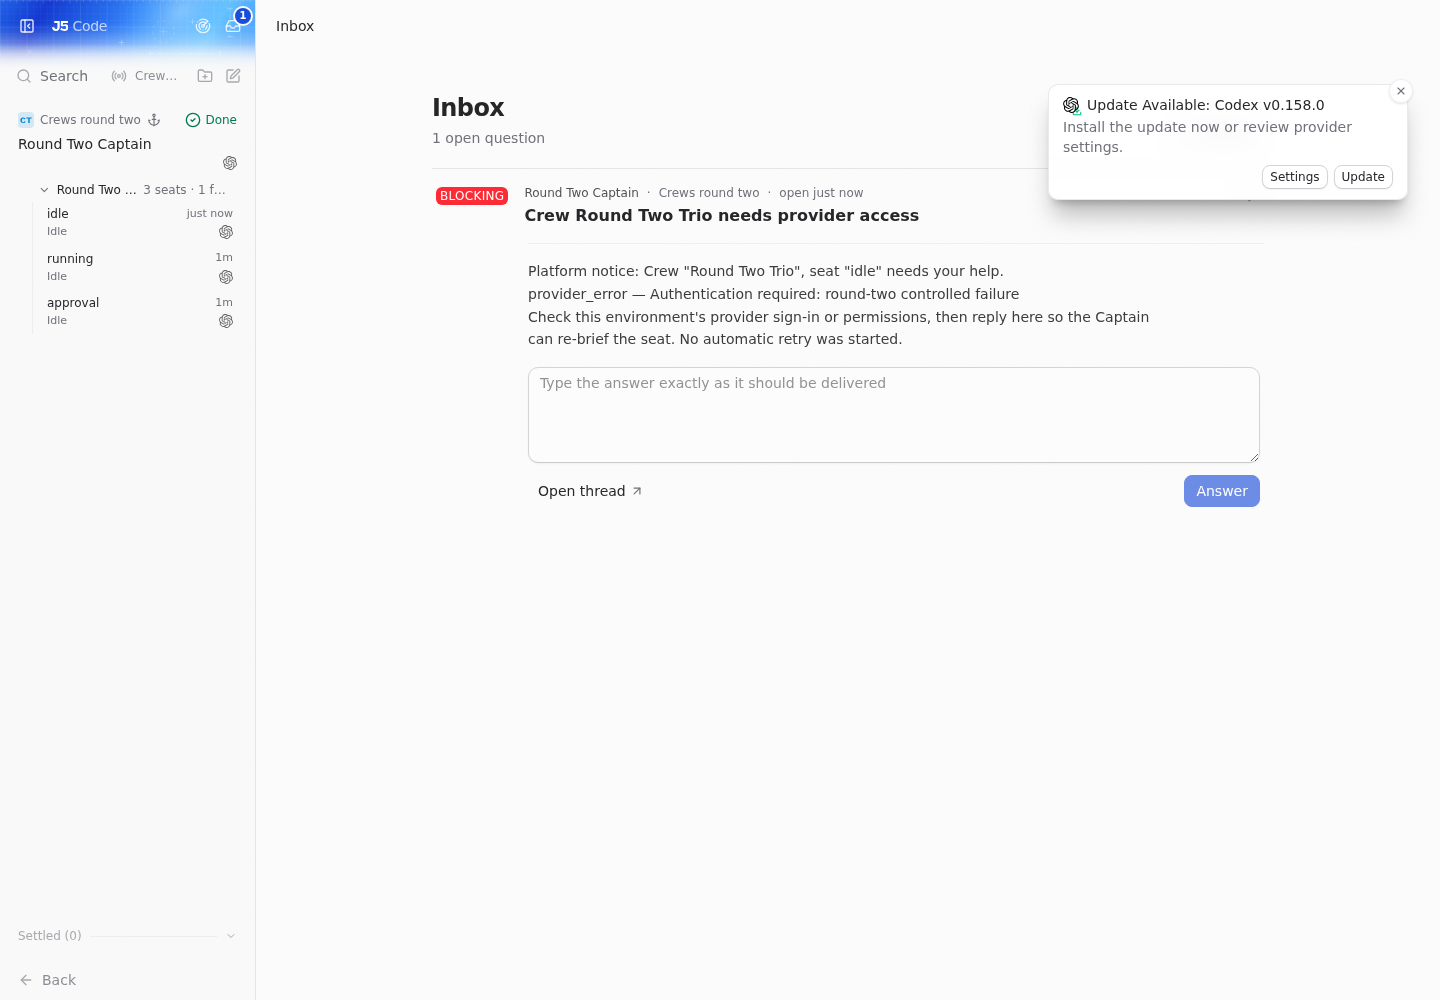
Alert wake — pass: a controlled authentication failure reached the Inbox without another send or a manual worker drain. The delivery committed 99 ms after creation, on its first attempt.
Test scope: real Codex Captain and seat threads, with controlled terminal events and artifact fixtures in isolated copied state. The handoff comparisons used a test-only cursor marker to prevent the separately reported historical replay bug #349 from contaminating the cards. The alert-wake test did not use that workaround. |
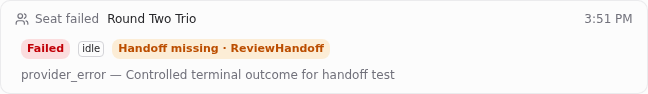
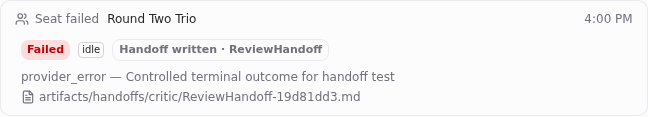

Conflict in the J5 migration list: #292's migration 020 now sits on j5/main, so 020 and this branch's 021 both stay, in id order.

Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
2 participants


Important
This PR is part of the Crews stack. Merge top to bottom, one at a time, and let each land on
j5/mainbefore the next. #292 isn't in the stack but has to merge before #313.fix(crews): no seat launches into a retired Crew or under a gone Captain #271: No seat launches into a retired Crew or under a gone Captain✅ mergedfix(crews): unit stop and archive finish over a seat that was never created #279: Unit stop and archive finish over a seat that was never created✅ mergedWhy #292 goes first: J5 migrations run in id order, and the migrator skips any id at or below the newest one a database has already applied. If #313's migration 021 ships before #292's 020, 020 never runs on that database.
Problem
Two Crew notices could state things the platform never checked (#225, #226). A seat's finish notice told the Captain a handoff was "missing" when the file only failed to read, and recorded that so no retry corrected it. A seat's sign-in or permission failure was appended to whatever ask the Captain had open with me, so answering my own question closed the alert with it.
What I changed
apps/server/src/j5/a2a/CrewSeatFinishNotifier.ts→handoffFact: only anot_foundread yieldsmissing; any otherArtifactWorkspaceErrorfails the notice.apps/server/src/j5/a2a/crewFailureAlert.ts: one alert exchange per Crew, ids underCREW_ALERT_EXCHANGE_PREFIXplus the URI-encoded Crew id; the reuse lookup matches only that Crew's prefix.apps/server/src/j5/a2a/migrations/020_CrewAlertExchanges.ts: recreatesj5_a2a_exchange_open_pair_idx, excluding alert ids.apps/server/src/j5/a2a/SendService.ts: the "join an open exchange" lookup for a new ask skips alert exchanges.Why this shape
The ledger allowed one open exchange per sender and receiver (migration 008), and the alert is sent as the Captain so replies route back to it. That index is why the old code joined the Captain's ask, and why the Captain couldn't ask me anything while an alert was open. I rejected sending the alert as the failed seat (my reply would go to a dead seat, not the Captain) and skipping the alert while an ask is open (I'd miss it in exactly that case). For #226 I chose retry over an explicit "handoff unavailable" fact: the platform shouldn't record a fact it didn't measure.
Invariants
Surfaces
Out of scope
agent-tools.mdseat-finish paragraph.Upgrade and data
Migration 020 drops and recreates one partial index; no rows change. Open alerts in the old id format (
exchange:j5-crew-human-alert:<runId>) match the prefix, so they're exempt too, and new failures open a fresh per-Crew alert beside them.Verification
vp test run apps/server/src/j5/a2a: 338 passed, 1 skipped.crewFailureAlert.test.ts(the module's first direct test) fails without migration 020 on the unique index.CrewSeatFinishNotifier.test.tscase: not-found, transient read error, recovery through the boot sweep, and unchanged-handoff dedup.Review focus
substrcheck inSendService: is anything else relying on one open exchange per pair?handoffFactnow failsnotifyIfFinishedafter the failure alert has already fired. That alert is idempotent per run, but check the ordering.Closes #225
Closes #226
Claude Opus 5.5 via Claude Code
🤖 Generated with Claude Code