Repository navigation
[Bug] pulsar-io EventLoopGroup is used in dispatchers to execute synchronized code and CPU intensive work #23865

Description

Search before asking
- I searched in the issues and found nothing similar.
Read release policy
- I understand that unsupported versions don't get bug fixes. I will attempt to reproduce the issue on a supported version of Pulsar client and Pulsar broker.
Version
All released versions
Minimal reproduce step
In dispatchers, topic.getBrokerService().executor(), the "pulsar-io" EventLoopGroup is used to execute synchronized code and CPU intensive work. The "pulsar-io" EventLoopGroup is intended to be the worker for Pulsar's ServerCnx Netty handler so that network connections remain responsive. Since dispatcher implementations contain multiple synchronized methods, blocking operations could impact all connections that are bound to the same IO thread.
Another potential problem that the solution causes unnecessary context switching since the current solution doesn't use a single thread for the scheduled jobs and the work that it performs.
What did you expect to see?
A pinned executor to be used for executing all operations for a dispatcher or replicator.
What did you see instead?
EventLoopGroup is used as executor and the thread could change for each execution.
Anything else?
No response
Are you willing to submit a PR?
- I'm willing to submit a PR!
Activity
lhotari commentedon Aug 20, 2025
this is a real performance issue with Pulsar. In #24623, I have added a solution for profiling test cases with Async Profiler with JFR integrated to it. It's possible to analyze the results with Eclipse Mission Control.
The lock analysis shows that dispatchers contribute to most blocking on pulsar-io threads:
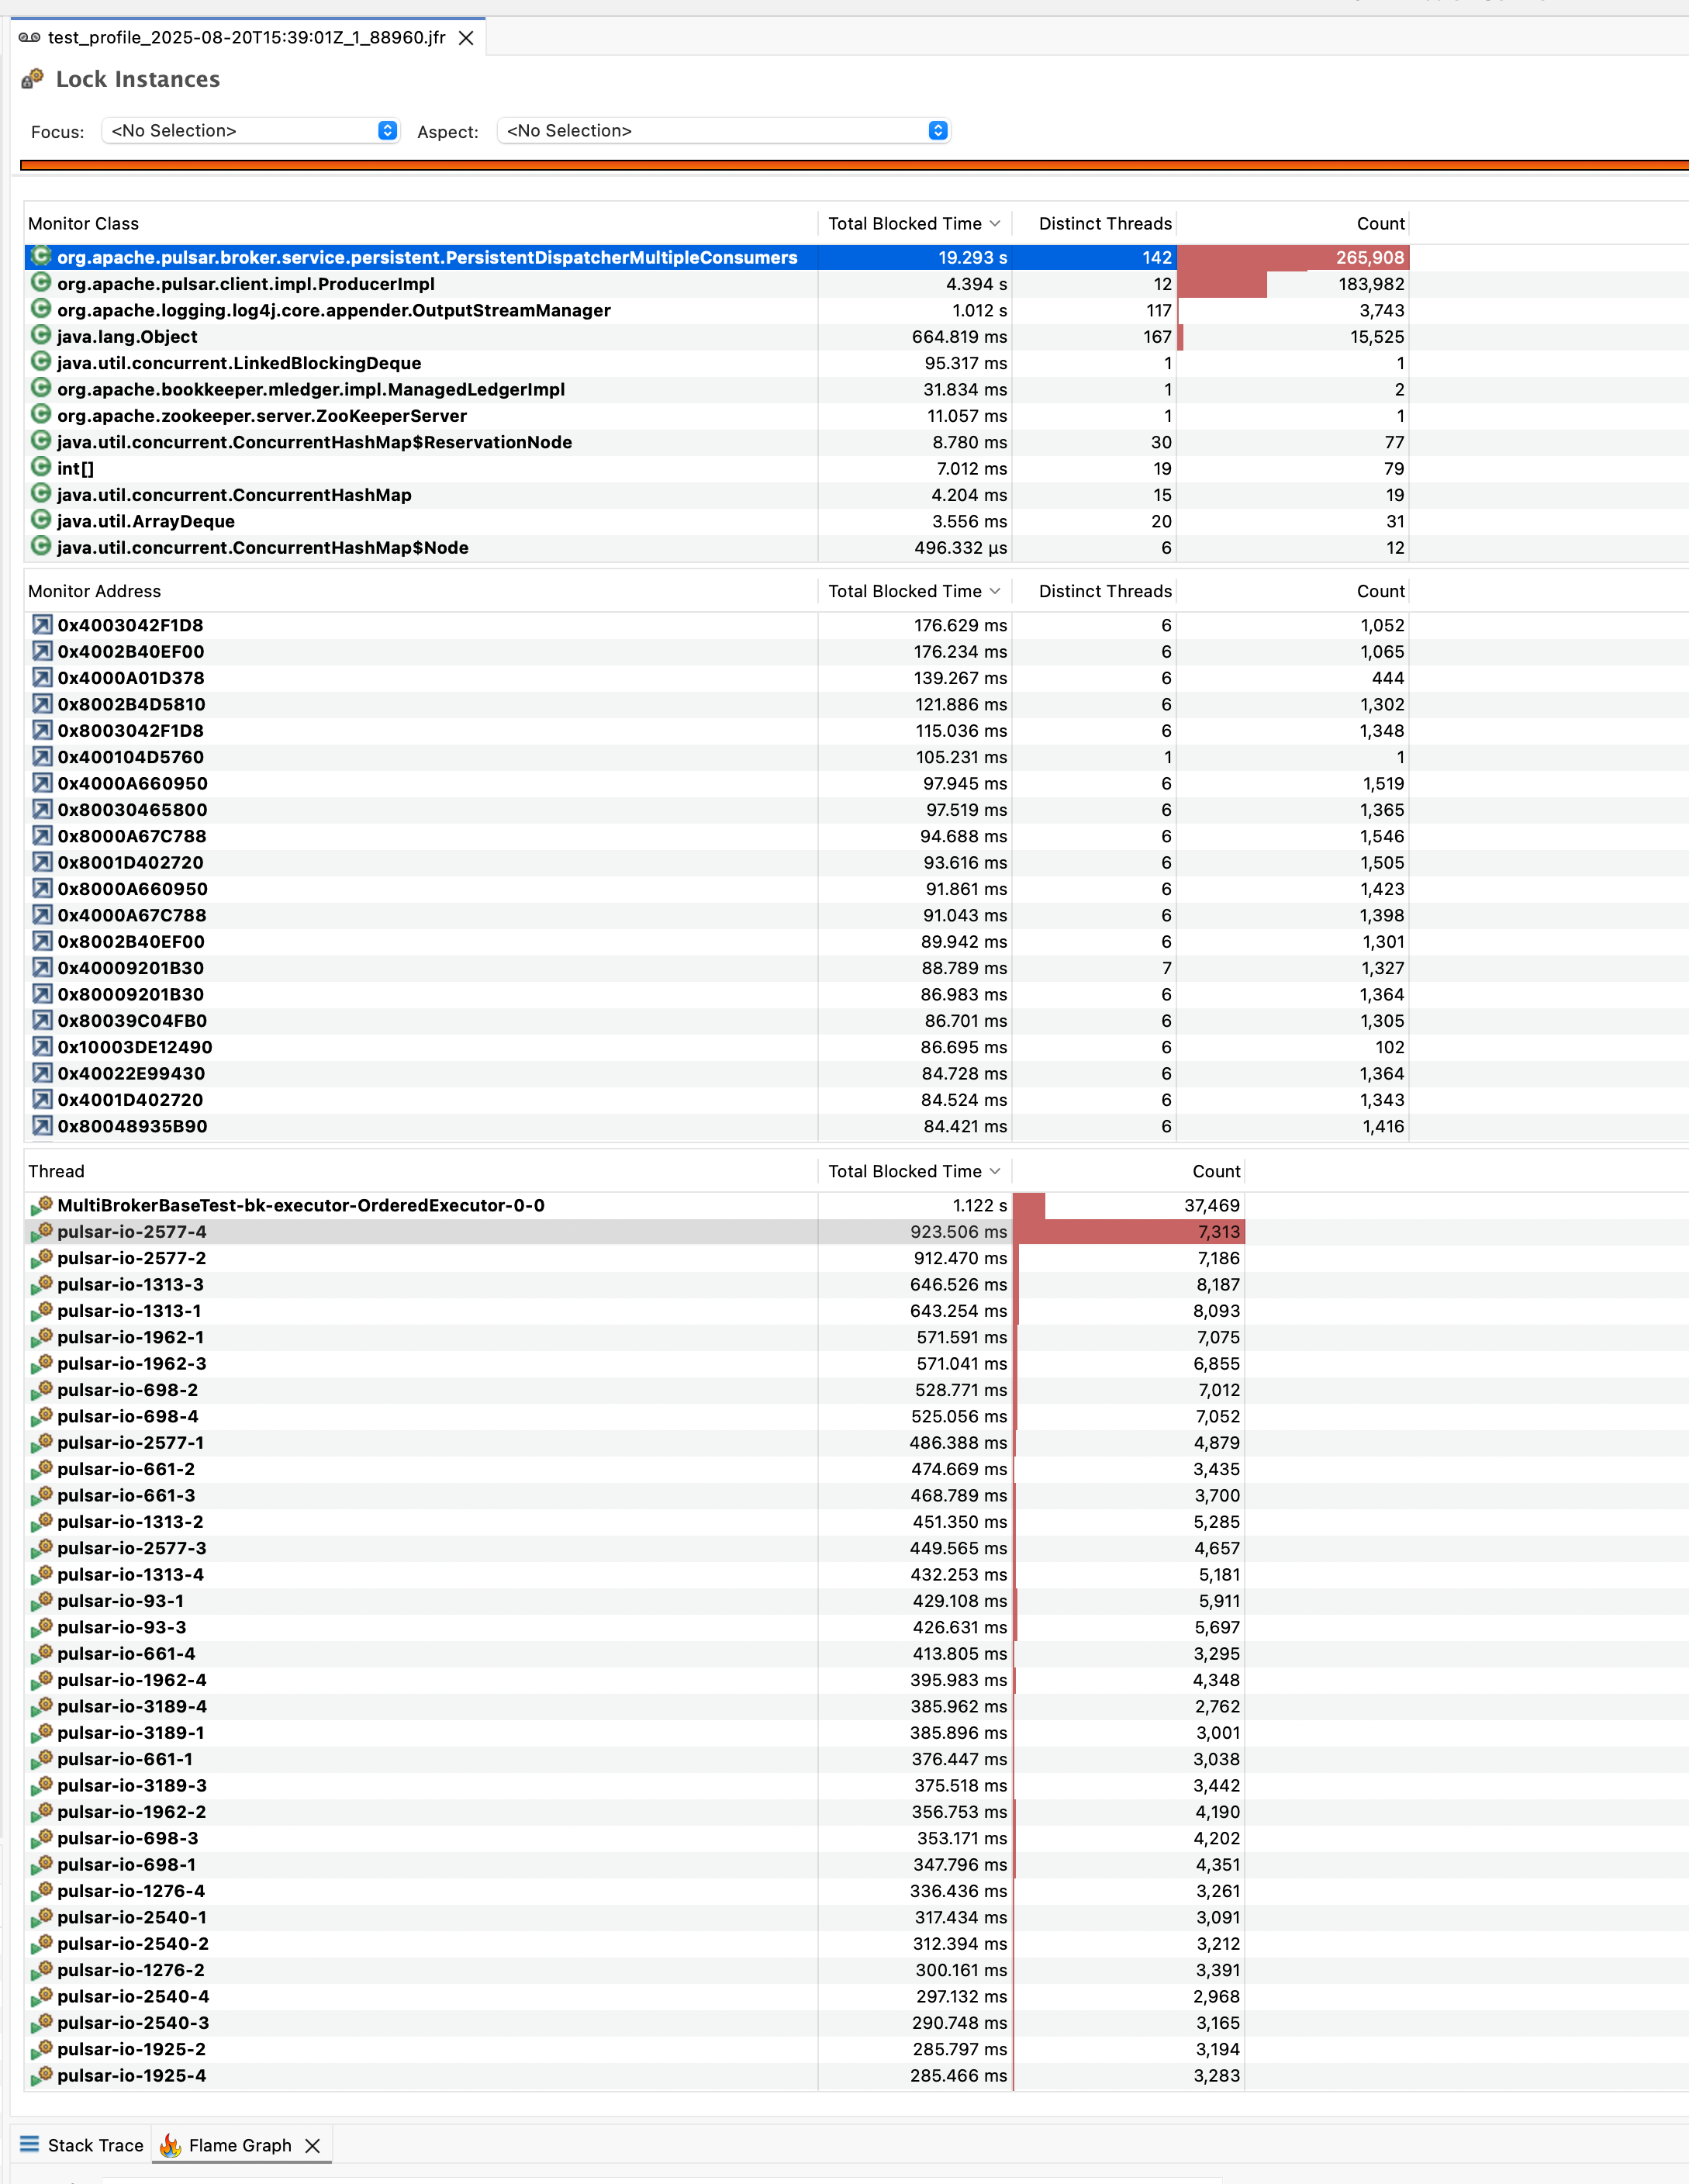
This is a problem since Netty IO threads shouldn't ever be blocked since one thread is used across multiple connections to handle the asynchronous IO events. Blocking will cause a "noisy neighbor" problem across connections.
merlimat commentedon Oct 24, 2026
Still present on master.
BrokerService.executor()returns the Netty worker group (pulsar-broker/src/main/java/org/apache/pulsar/broker/service/BrokerService.java:3622), and the dispatchers still schedule their synchronized read and flow work on it, for example the read reschedule inPersistentDispatcherMultipleConsumers.java:602-604and the flow handling at:330/:378, plusPersistentDispatcherSingleActiveConsumer.java:139/:439/:554andPersistentReplicator.java:340/:365. Only the dispatch step itself now uses a pinned topic-ordered thread (PersistentDispatcherMultipleConsumers.java:182). So blocking in these methods can still stall every connection bound to the same pulsar-io thread. The likely fix is to run each dispatcher's and replicator's scheduled work on one thread chosen from the topic-ordered executor, as the dispatch step already does.