


Agentic coding. Local models. On your Mac.
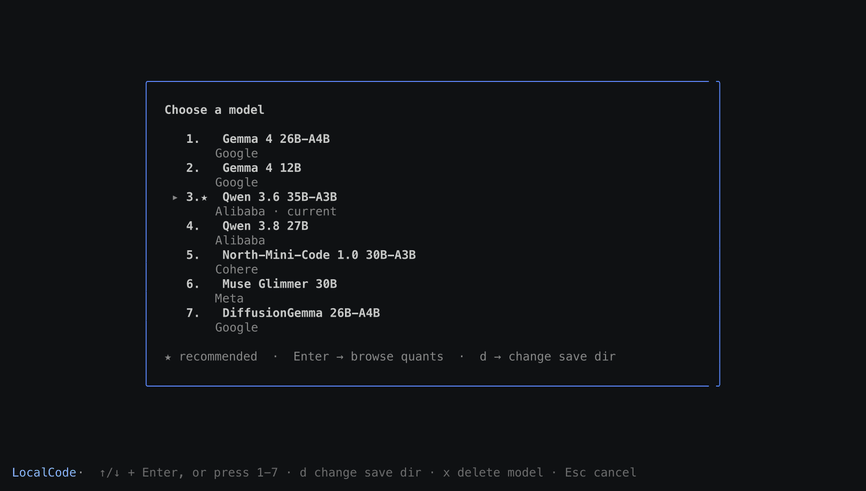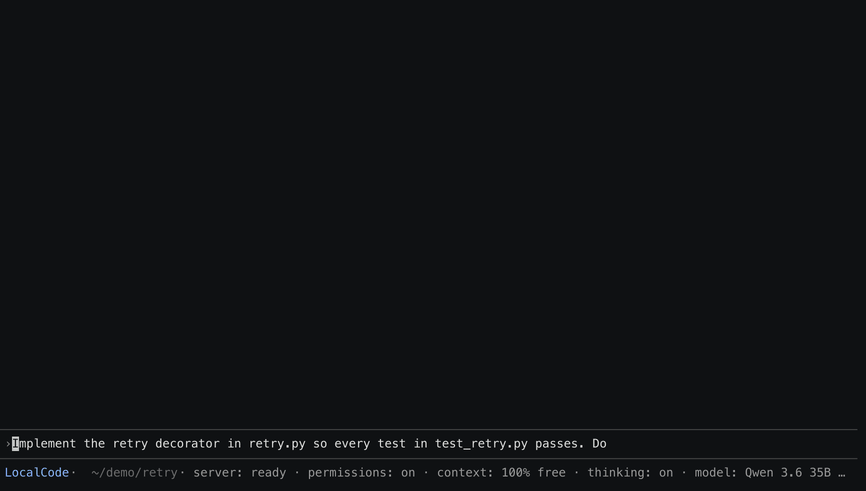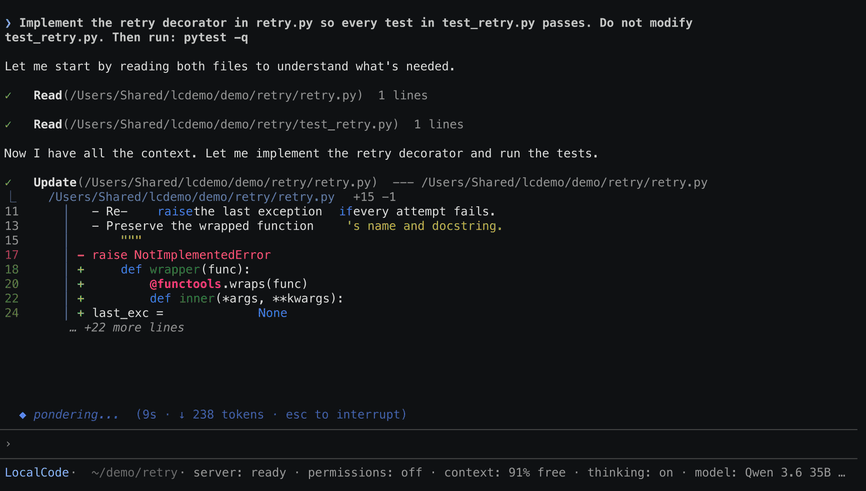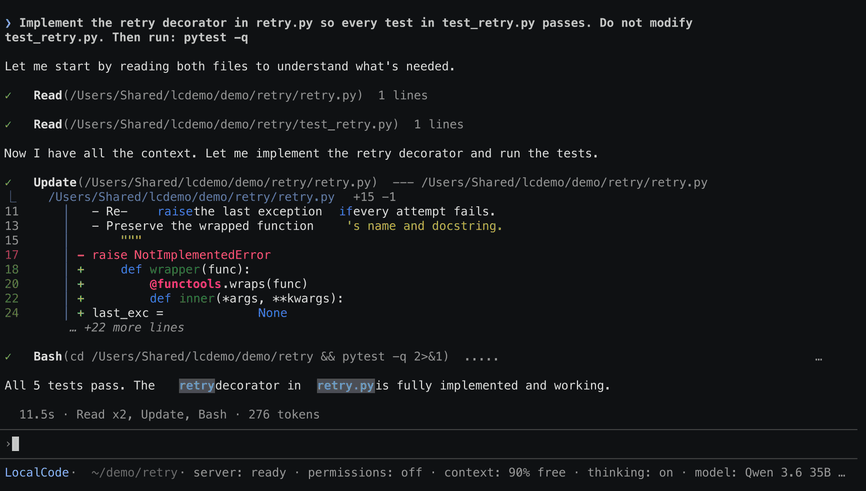
localcode runs an open-weight model on your Mac and uses it to read, edit and test your code. Model inference runs locally.
pip install -U localcode # or: uv pip install -U localcodeThe inference server ships inside the package. Nothing is compiled or cloned on your machine.
cd your-project
localcode
> Implement the retry decorator in retry.py so every test in test_retry.py passes. Then run: pytest -q
To use the running model from another local app, open /server or run localcode api for its
OpenAI compatible endpoint. See the Local API guide.
- Reads and edits files in your project
- Runs your tests, builds, Git and shell commands inside the project on its own, and asks before touching anything outside it
- Searches code by name, content or structure
- Scaffolds and launches apps, then checks that they respond
- Remembers the task across messages
- Mac with Apple Silicon, macOS 13 or newer
- 16 GB unified memory or more
- Python 3.10 or newer
- Disk space for LocalCode and your chosen model (download sizes below)
Choose from 10 models and 100+ quant options for coding, image input and typed decisions. Models download from Hugging Face. Downloads run in parallel and can resume if interrupted. Switch with /models.
| Model | Smallest download | Largest download | 16 GB: tokens/s | 16 GB: context | 128 GB: tokens/s | 128 GB: context |
|---|---|---|---|---|---|---|
| Gemma 4 12B | 4.2 GB | 23.8 GB | — | — | — | — |
| Qwen 3.8 27B | 6.2 GB | 31.5 GB | — | — | — | — |
| Underdog Saluki 27B 1.0 | 7.9 GB | 7.9 GB | — | — | — | — |
| North-Mini-Code 30B-A3B | 9.4 GB | 33.2 GB | — | — | — | — |
| Gemma 4 26B-A4B | 9.9 GB | 27.6 GB | — | — | — | — |
| Qwen 3.6 35B-A3B | 10.0 GB | 38.5 GB | — | — | — | — |
| Muse Glimmer 30B | 10.7 GB | 32.3 GB | — | — | — | — |
| DiffusionGemma 26B-A4B | 16.8 GB | 50.5 GB | — | — | — | — |
| OpenJev 27B (decisions) | 19.4 GB | 53.8 GB | — | — | — | — |
| Kolibri 1 78B-A3B (experimental) | 28.6 GB | 47.5 GB | — | — | — | — |
Download sizes checked on Hugging Face on 12 October 2026; optional vision and draft files are extra. — = not measured on that RAM tier. Speed and usable context also depend on the Mac's chip and selected quant; RAM alone does not determine them.
Inference is local. Three features use the network: model downloads, the web_search and web_fetch tools, and any MCP servers you add. See Network Boundary for the full list.
Powerful, personal AI should work for everyone, on any device, anywhere. That means running it locally. localcode is a first step.
To sponsor localcode, reach out.
Installation diagnostics: localcode doctor. See compatibility tests and local hardware verification.
See CONTRIBUTING.md.
Apache 2.0. See LICENSE.